Sigrid leads the customer support team at a company that makes accounting software. For six weeks, her team piloted an AI assistant that answers simple tickets before a person picks them up. At the review meeting, Darragh, the product manager who championed it, opens with a slide.
"Three wins," he says. "Satisfaction is up for French-speaking customers. Repeat contacts are down on Thursdays. And billing tickets are being closed eleven percent faster. The assistant works."
Sigrid looks at the support dashboard on her laptop. It tracks about thirty numbers. Most of them haven't moved. Two got slightly worse. Darragh's three wins are real numbers, but nobody said before the pilot that French satisfaction or Thursday repeat contacts were what the assistant was supposed to change.
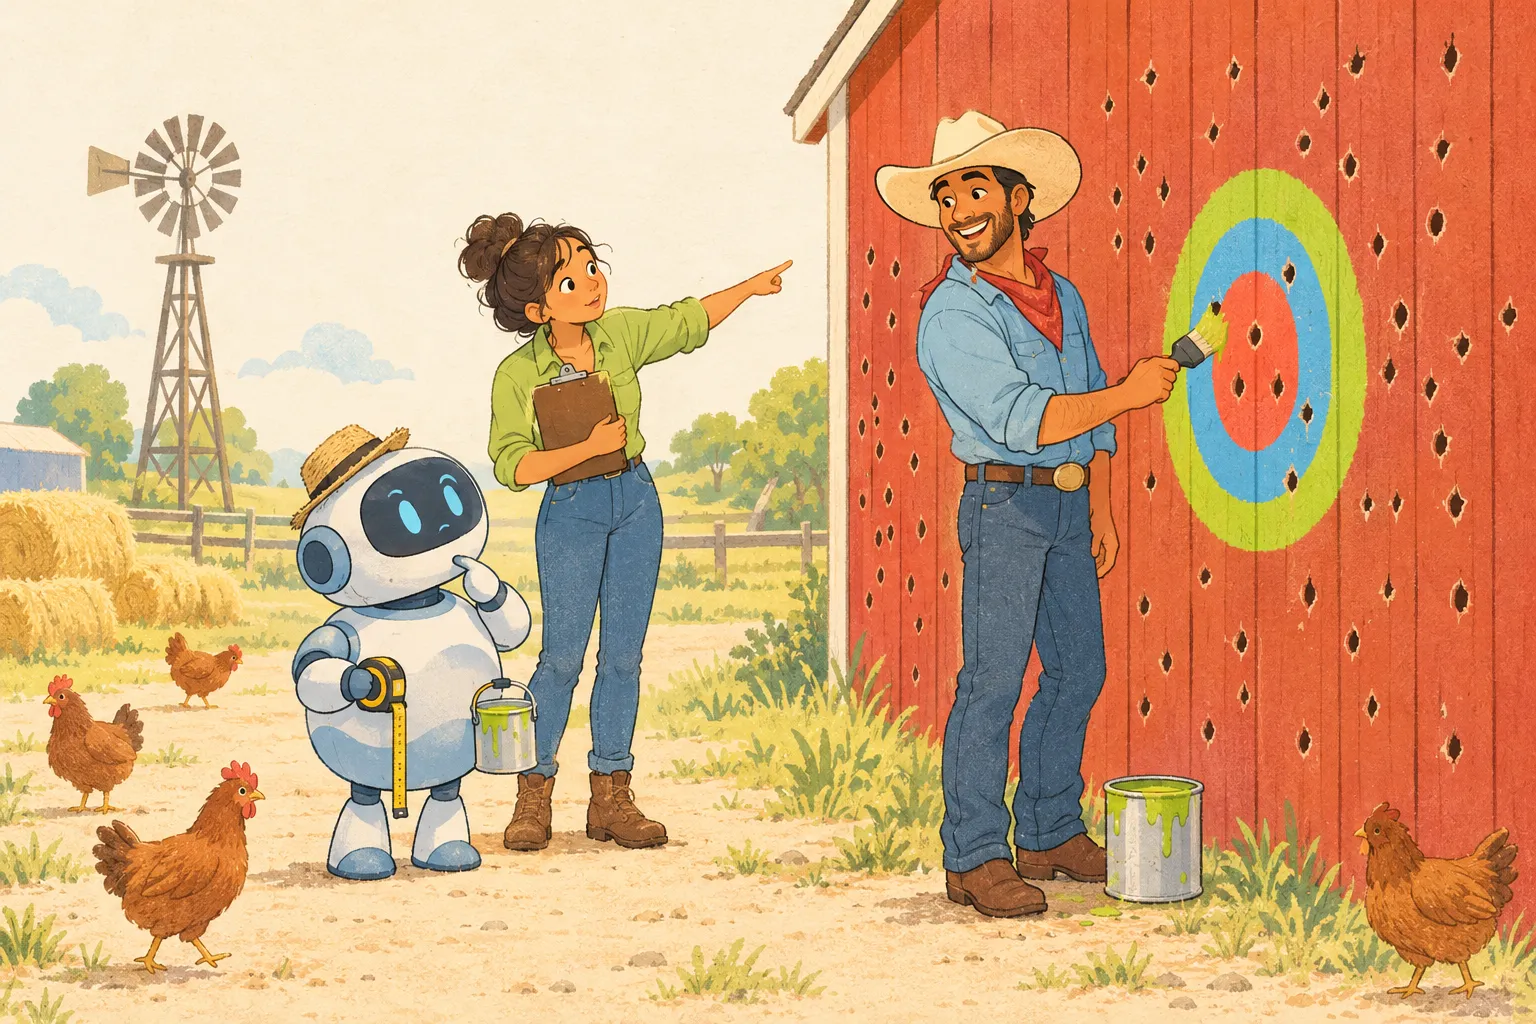
Darragh didn't lie. He shot at the barn, then painted the target around the holes. That move has a name: the Texas sharpshooter fallacy. This guide covers what it is, why it's so convincing, where it shows up, and the questions that tell a real pattern from a painted one.
What is the Texas sharpshooter fallacy?
The Texas sharpshooter fallacy is picking out a pattern in data after you've seen the results, then treating it as meaningful, or as if it had been predicted all along. You focus on the cluster of hits and ignore the misses around it. The data was used twice: once to find the pattern and once to "prove" it.
The name comes from an old joke. A man fires a gun at the side of a barn, then walks over and paints a target around the tightest group of holes. Everyone who sees the barn later thinks he's a remarkable shot.
Three features give it away:
- The target came after the shots. The claim was formed by looking at the results, not before them.
- Many places to look. There were lots of numbers, groups, dates or locations where a pattern could have turned up.
- The misses are left out. Nobody mentions the twenty-seven metrics that didn't move.
It's entry 21 in our guide to logical fallacies. This article goes deeper, because the hard part is noticing when you're the one holding the paintbrush.
Where the name comes from
Nobody knows who first told the joke. One of the earliest known uses in print is a 1977 paper on Hodgkin's disease in the medical journal Cancer, by the epidemiologist Seymour Grufferman. Writing about clusters of cases identified after the fact, he noted that "such a posteriori clusters are analogous to the story of the Texas sharpshooter," and that they don't let you determine whether a cluster is more than chance.
That's where the idea found its most serious use: in epidemiology, where the first question about any cluster is whether it would be surprising if nothing unusual were going on.
Why random data looks like a pattern
Here's the part that surprises most people: randomness is clumpy. If you scatter things at random, they don't spread out evenly. Some spots get several, and some get none. Our brains read those clumps as a message.
The best illustration comes from wartime London. During the flying bomb attacks of the Second World War, people often claimed the bombs were landing in clusters. In 1946, an actuary named R. D. Clarke published a short paper in the Journal of the Institute of Actuaries testing that belief.
He divided 144 square kilometers of south London into 576 squares of a quarter square kilometer each and counted the hits. There were 537 bombs in the area. If the bombs fell purely at random, statistics predicted about 227 squares with no hits and about 7 squares with four. The actual counts were 229 and 7. The match was close all the way down the table. As Clarke put it, the result "lends no support to the clustering hypothesis."
Some squares really were hit four or five times. But that is exactly what chance produces. The meaning was painted on afterwards.
Look in enough places and something will hit
The second reason the fallacy works is simple arithmetic. If each number on a dashboard has a 1 in 20 chance of showing a "notable" change by luck alone, and you check 30 of them, you should expect one or two to look notable even if nothing real happened. Statisticians call this the problem of multiple comparisons: the more questions you ask of the same data, the more answers you get by luck.
Texas sharpshooter fallacy examples
You've seen most of these. In every one, the pattern was found by looking, then presented as if someone had aimed at it.
| Where | What the sharpshooter says | The painted target | The misses left out |
|---|---|---|---|
| Work dashboard | "The new tool boosted three key metrics!" | Three metrics picked after the results came in | The 27 metrics that didn't move or got worse |
| Supplements | "Our study found it improves sleep quality." | One of many outcomes measured | The other outcomes that showed nothing |
| Predictions | "This pundit called it: five predictions came true!" | Five hits chosen after the fact | The fifteen predictions that missed |
| Investing | "This strategy would have tripled your money since 2015." | A rule tuned to fit past prices | The hundreds of rules that were tested and dropped |
None of these patterns is necessarily false. The fallacy is treating a pattern found after the fact as if it were already proven.
Cancer clusters: when the stakes are high
This isn't just a puzzle for statisticians. When a community sees what looks like a cluster of cancer cases, people are frightened, and they deserve a real answer.
According to the US National Cancer Institute, a cancer cluster is a greater than expected number of cancer cases among a group of people in a defined area over a specific time. The NCI also notes that because cancer is common, cases can appear to cluster even when there is no connection between them. It cites a review (Goodman and colleagues, 2012) of 576 cancer cluster investigations carried out over 20 years. In only 72 could an increase in cancer be confirmed. Only 3 of those could be linked to a possible exposure, and in just one was a clear cause identified.
That doesn't mean worried neighbors are being silly, or that environmental causes never exist. It means the cluster alone is a question, not an answer. The cause has to be tested, not read off the map.
Texas sharpshooter vs cherry picking and other related errors
The sharpshooter fallacy has close relatives. They often show up together, but they're worth telling apart, because each needs a different question.
| Error | What happens | The question that catches it |
|---|---|---|
| Texas sharpshooter | A pattern is found in the results, then presented as the point | "Was this predicted before the data came in?" |
| Cherry picking | Supportive evidence is shown, the rest is hidden, to back a claim made in advance | "Can we see all of it?" |
| Confirmation bias | You notice and remember what fits what you already believe | "What would I expect to see if I were wrong?" |
| Post hoc fallacy | B followed A, so A must have caused B | "What else changed at the same time?" |
| Survivorship bias | You only see the cases that made it through | "Who is missing from this picture?" |
| Hasty generalization | A broad rule is drawn from a few cases | "How many cases is this based on?" |
| Clustering illusion | Random clumps look like they must mean something | "How clumpy would this look by pure chance?" |
The cleanest way to tell the sharpshooter from cherry picking is timing. A cherry picker has the target first and hunts for holes that support it. A sharpshooter has the holes first and draws the target to fit them. In practice, the two often blur.
When a pattern found after the fact is fine
Here's what most explanations skip. Finding patterns in data you've already collected isn't a sin. It's how a lot of discovery starts. The mistake is skipping the next step.
A pattern found by looking is a hypothesis. It becomes a finding only when it's tested on data that wasn't used to find it. In research, presenting a pattern found afterwards as if it had been the plan all along has its own name: the social psychologist Norbert Kerr called it HARKing, short for "hypothesizing after the results are known," in a 1998 paper. Kerr's point wasn't that exploring data is wrong. It was that dressing up an exploration as a confirmed prediction misleads readers.
| Honest exploration | Texas sharpshooter |
|---|---|
| "We noticed billing tickets got faster. Let's test whether that holds." | "Billing tickets got faster. The tool works." |
| Says how many things were checked | Mentions only the hits |
| Tests it on new data | Uses the same data to find it and prove it |
| Would accept it if the pattern disappeared | Finds a new pattern if the old one disappears |
When a sharpshooter's pattern doesn't hold up, they rarely say "I was wrong." They find a different cluster on the barn, which is a close cousin of moving the goalposts.
How to spot it: five questions
You don't need statistics training to catch a painted target. These five questions do most of the work.
1. When was the target drawn?
"Did anyone say before the results that this was what we'd look for?" If the claim was written down in advance, a hit means something. If not, it's a lead, not proof.
2. How many places were there to look?
"How many metrics, groups or time periods did we check?" One hit out of one is impressive. One hit out of thirty is about what luck delivers.
3. Where are the misses?
"What about the ones that didn't change?" The full barn is the most useful thing you can ask to see.
4. Is the group oddly specific?
"French-speaking customers on mobile in the first two weeks" is a warning sign. The more conditions a pattern needs, the more likely it was carved out of noise.
5. Does it hold in new data?
This is the decisive one. Check the pattern somewhere it wasn't found: the next month, another office, another sample. A real pattern tends to repeat. A painted one usually fades.
How to respond without starting a fight
"That's the Texas sharpshooter fallacy" is accurate and almost never helps. People hear "you're cheating" and dig in. Treat the pattern as a promising lead instead.
A simple pattern: credit the finding, ask about the misses, offer a test.
| What you hear | What you can say |
|---|---|
| "Look, three metrics went up!" | "Nice. How many did we track in total? I'd like to see the ones that didn't move too." |
| "The data clearly shows this group responds best." | "Interesting. Was that the group we planned to look at, or did it stand out afterwards?" |
| "So many people on our street are sick. It has to be something here." | "That's worth reporting to the health department. They can check whether it's more than you'd expect by chance." |
| "The backtest shows this strategy beats the market." | "How many strategies were tested before this one? How has it done since it was chosen?" |
With someone you'll see again tomorrow, the third step matters most. "Let's test it properly" gives the other person a way to be right for real.
Worked example: Sigrid and the AI assistant
Sigrid didn't tell Darragh his slide was a fallacy. She said, "Some of these might be real, and if they are, I want to know. Can we run a second phase and decide in advance what counts?"
They agreed on a short plan before the second phase started:
| Question | What they agreed |
|---|---|
| What is the assistant supposed to change? | Time to first response, and how many tickets get solved without a person |
| What would count as success? | A clear improvement on both, over four weeks |
| What would count as failure? | No change, or worse satisfaction scores overall |
| What about the three wins? | Tracked as hypotheses: if they're real, they should show up again |
| What gets reported? | Every metric on the dashboard, not just the good ones |
After four weeks, the results were mixed. Billing tickets got faster first responses and were more often solved without a person, so that early win had been real. Other tickets didn't change. The French satisfaction bump and the Thursday repeat contacts were gone, the way luck usually goes.
The company kept the assistant for billing tickets and dropped it for the rest. Darragh got a result he could defend to anyone.
How to catch it in your own thinking
Everyone paints targets. It feels like noticing, not like cheating.
- Write your prediction down first. Before you check the results of a test, a launch or a new habit, write one sentence: "If this works, I expect to see X." It takes thirty seconds.
- Count your shots. When something stands out, ask how many other things you looked at. Be honest about the number.
- Report the misses. When you share a win, mention what didn't change. People will trust your wins more.
- Watch for stories that are too neat. If a pattern perfectly fits what you hoped for, that's when to look hardest.
How to practice this with AI
Spotting a painted target is harder when the slide is in front of you and the presenter is excited. A debate lets you practice the questions first. On Debatly, several AI models and characters argue different sides of your question over several rounds, you can step in at any point, and a judge gives a verdict with reasoning.
- Put a pattern on trial. Type a claim you've seen into the debate room, for example "Our new onboarding emails increased retention among customers who signed up on weekends." Ask one side to defend it and the other to question how it was found.
- Bring in a data person. Ask Sofia, the data scientist, how many comparisons might have been made and what a fair test would look like. She's useful for turning a lead into a plan.
- Ask a skeptic for the misses. Have Viktor, the skeptic, list what the claim leaves out: other metrics, other groups, other time periods.
- Read the verdict. Judge Alex explains which arguments carried the round. Check whether the winning side had a prediction made in advance or just a good-looking cluster.
When Sigrid ran Darragh's slide as a debate, the questioning side asked in the first round how many metrics the dashboard tracked. She walked into the meeting knowing how to ask it kindly.
An honest limit
AI models can't see your data, and they can't tell you whether a pattern is real. Only a test on new data can do that. They are also good at inventing a plausible story for any pattern you hand them, which is the sharpshooter's paintbrush in a new form. And many models lean toward whatever you seem to believe already (see why AI agrees with you). Use the debate to sharpen your questions and design the test. The answer still has to come from the data.
Draw the target first
The Texas sharpshooter fallacy wins by making a pattern found by chance look like a prediction that came true. The fix is plain: decide what you're aiming at before you look, count every shot, and check whether the pattern holds somewhere new.
This week, when someone shows you a striking result, ask one question: "Was this what we were looking for before we looked?" If you have a pattern you're excited about, run it as a debate on Debatly and let the other side look for the misses first. Give it a try. Plans are on the pricing page.
“Texas Sharpshooter Fallacy: Examples and How to Spot It”